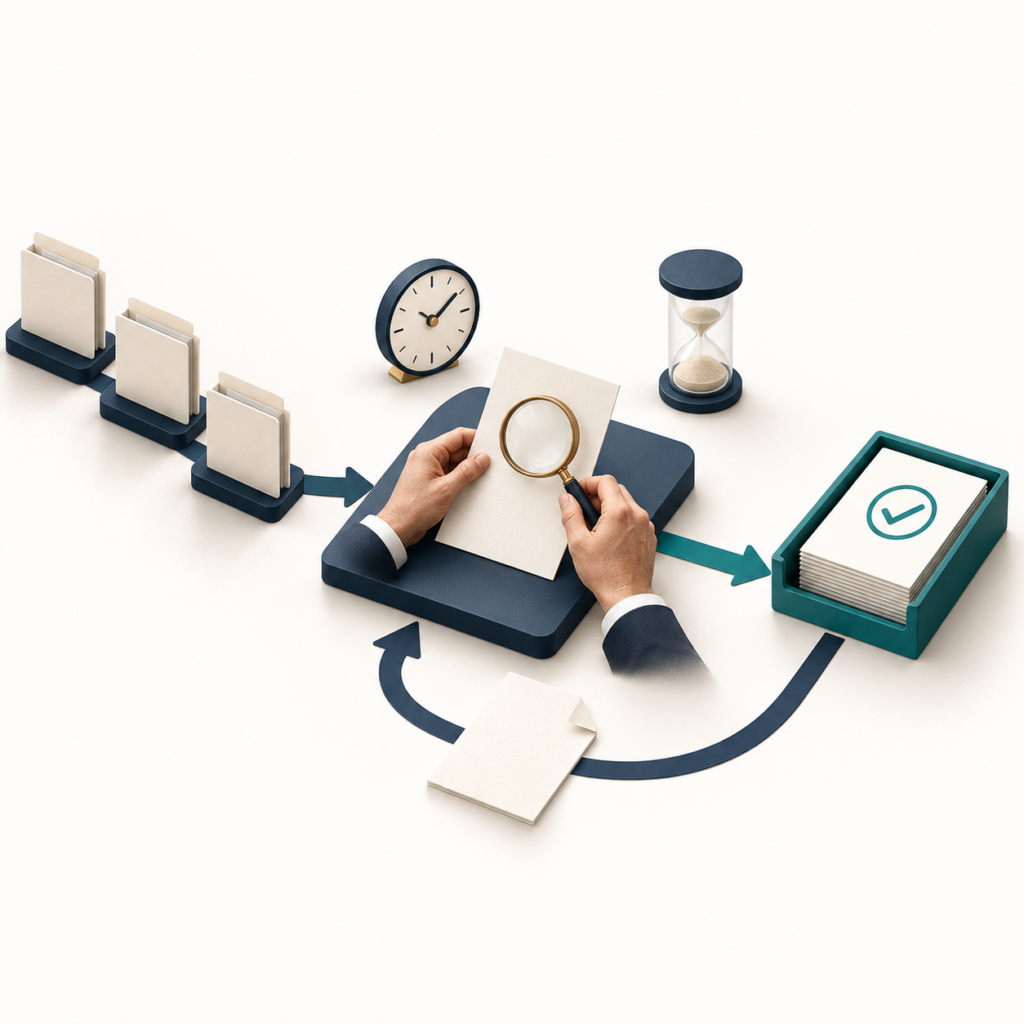
An AI assistant produces a service-response draft in minutes. That looks promising. Before expanding the pilot, an operations leader needs to know what happened next: how much checking was required, whether corrections delayed the response, and whether the customer received an acceptable answer.
Useful AI pilot metrics follow the work through to its accepted outcome. NIST’s ARIA evaluation planning manual, published on September 18, 2026, brings together model testing, red teaming and user testing. That wider evaluation perspective is a timely reminder to examine an application in use. The operational scorecard below is a practical proposal for your pilot, not a NIST standard.
Define the outcome before measuring speed
Start with one bounded workflow and its accountable owner. For a service-request pilot, the boundary might run from receipt of a request through correct assignment and an accepted response. Retain required human sign-off. Agree what makes a response complete and acceptable before collecting results.
Write down the starting event, completion condition, included request types, review period and person responsible for the data. Define how incomplete requests and unusual cases will be recorded. A shared definition prevents one team from counting a generated draft as finished while another is still correcting it.
Set the intended operating outcome alongside quality and control conditions. For example, the team may want less human effort per accepted request while maintaining the agreed response standard. The process owner should approve the measures and decision criteria before seeing the pilot results.
Five AI pilot metrics for the whole workflow
Use a small scorecard that separates hands-on work, waiting and acceptable outcomes. A spreadsheet is enough to begin; a dashboard becomes useful when definitions and data collection are stable.
| Measure | Working definition | Decision it informs |
|---|---|---|
| Total human effort | Preparation, review, correction and exception-handling minutes per accepted case. Keep these time buckets mutually exclusive. | Has the workflow reduced human work, or moved it to another step? |
| End-to-end elapsed time | Time from request receipt to accepted response, including queues and waiting. | Does the requester receive an acceptable response sooner? |
| First-pass acceptance | Cases accepted at the first review without correction, divided by all cases receiving a first review. | Is the initial output useful enough for its intended purpose? |
| Rework and exceptions | Number and share of attempted cases requiring correction or exception handling; record the associated effort and reasons. | Which recurring problems need a process or tool change? |
| Quality and control failures | Record unacceptable outputs and missed required controls, including severity, owner and required response. | Is continuing or expanding the pilot acceptable? |
Define a correction for this workflow, such as fixing a wrong request category or unsupported response statement. Distinguish it from a routine review. If a case has several corrections, report both the affected-case count and the number of corrections.
Report failed, abandoned and still-open cases separately, including effort already spent on them. Completed-case averages must not make unfinished work disappear. Keep those counts beside the accepted-case results at every review.
Count the work that faster drafts can hide
Illustrative example, not client results: suppose comparable accepted service requests require 30 minutes of total human effort before the pilot. During the pilot, the same workflow requires:
- 8 minutes to prepare the AI-assisted response;
- 18 minutes to review it;
- 6 minutes to correct it.
The total is 32 minutes. These are separate, non-overlapping activities measured within the same workflow boundary and against the same accepted output. Faster preparation has not reduced total human effort in this example.
This arithmetic says nothing about typical AI performance, elapsed-time improvement or financial return. It identifies a question to investigate: why does review require so much work? Examine source information, task instructions and acceptance criteria. Removing required review to improve the time figure would undermine the comparison.
Make the comparison fair
Compare cases with similar complexity, request mix and workload. Show the number observed, the dates covered and each case’s status. If the pilot receives only straightforward requests while the baseline includes difficult exceptions, present those groups separately.
Record learning-period effort and one-time setup alongside ongoing operating effort. Separate them so readers can understand each, without hiding either. Note changes in staffing, routing rules or service expectations that might also affect results.
Use a typical value and a view of the spread, such as the median and range, where an average conceals variation. Small samples can point to a bottleneck; they do not establish certainty about future performance.
The Measure function in NIST’s AI Risk Management Framework emphasizes contextual measurement, documented evidence and testing before deployment and during operation. Apply that discipline to the pilot’s review routine. This operating scorecard complements, but does not replace, appropriate safety and security testing.
How This Helps Business Leaders
Put a decision date, decision owner and evidence pack on the calendar. The review should lead to an action with an owner:
- Scale: agreed operating outcomes and all applicable quality and control conditions hold, with a plan to monitor the expanded workflow.
- Revise: a specific bottleneck is understood, a bounded change is proposed, and the team will retest it.
- Stop or contain: a serious control failure or unacceptable error remains unresolved.
Set thresholds with the accountable process owner. A universal percentage target cannot account for different request types, consequences or review requirements.
Keep released capacity separate from cash savings. Less effort may give a team more time for other work; a realized financial benefit needs its own evidence. AI pilot metrics should make the decision traceable, with human accountability for what happens next.
How Pragy Consulting Can Help
The Pragy Workflow Intelligence Sprint focuses on one bounded operational workflow with an accountable owner. Its scope includes baseline definition, workflow design, human review and control points, testing and acceptance, pilot measures and handover.
The Workflow Design Sprint produces a build-ready blueprint. The Workflow Pilot Build Sprint configures and tests a bounded pilot using approved tools within agreed scope. Production deployment depends on explicit scope and client access, security, licensing, testing and release approvals. No particular operating or financial improvement is guaranteed.
Explore the Workflow Intelligence Sprint to discuss one workflow, its baseline and the evidence your team needs before a wider rollout.